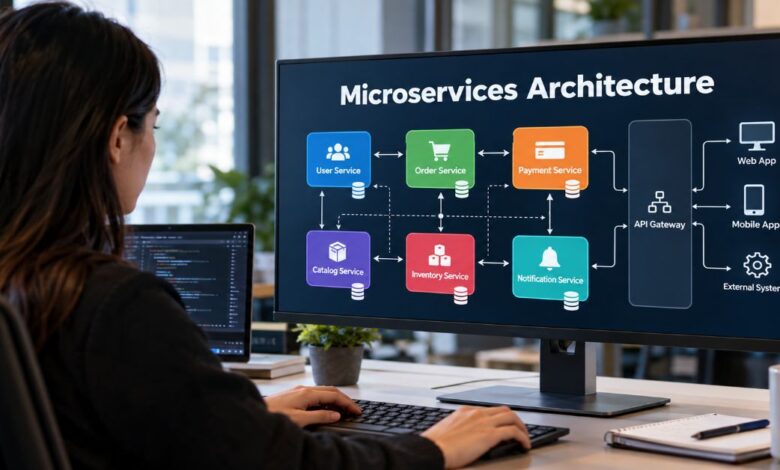
Microservices Architecture is a strong fit when a system has clear business boundaries that must be deployed, owned, or scaled independently; it is a poor fit when teams mainly want smaller code files. The sharpest 2026 contradiction is that the platform around microservices is more mature than ever, yet the core distributed-systems costs – network failure, data consistency, observability, and cross-team coordination – remain unavoidable. That distinction matters because most search results still begin with the same promise: split a large application into small services and gain agility, resilience, and scale. Those benefits are real, but they are conditional. A service that cannot be changed without coordinating with three other services is not operationally independent, no matter how small its repository is. A service that reaches directly into another service’s database is not truly autonomous. And a team that cannot trace one user request across the system will struggle to debug failures that a monolith would expose in one process.
The useful question, then, is not whether microservices are modern. It is whether the application’s change patterns, business boundaries, traffic profile, data rules, and operating model justify paying the distributed-system tax. This guide approaches the subject from that decision point. It explains what the architecture actually changes, how to draw service boundaries, why data ownership matters, what fails in production, when a modular monolith is better, and how to migrate without turning a working system into a network of tightly coupled services.
What Microservices Change – and What They Do Not
A microservice is not defined by a fixed line count, a separate Git repository, or a container. The useful definition is behavioral: it is an independently deployable unit built around a business capability, with an explicit contract and enough ownership of its data and runtime behavior to change without forcing coordinated releases elsewhere. Martin Fowler and James Lewis helped formalize this view by emphasizing business capabilities, decentralized data management, automation, and design for failure.
This is why the word micro can mislead. The target is not the smallest possible service. The target is the smallest boundary that remains coherent. If an order service cannot complete a meaningful change without a simultaneous release of inventory, payment, and customer-profile services, decomposition has created distribution without autonomy.
The architecture also changes the unit of failure. In a monolith, a function call is local and generally succeeds or throws immediately. In a distributed system, every call crosses a boundary that can be slow, unavailable, duplicated, reordered, or partially completed. That makes timeouts, retries, idempotency, circuit breaking, message durability, and tracing part of application design rather than infrastructure trivia.
The three main architecture choices can be compared by the kind of independence they create, not by trendiness or service count.
| Architecture | Deployment unit | Data boundary | Best fit | Main risk |
| Monolith | One deployable application | Usually one shared data layer | Small teams, cohesive domains, simple operations | Code coupling can grow if modularity is weak |
| Modular monolith | One deployment with enforced internal modules | Shared or module-owned schemas | New products and domains that need clean boundaries without distributed overhead | Module boundaries can erode without governance |
| Microservices | Multiple independently deployable services | Service-owned data contracts | Independent scaling, release cadence, ownership, or reliability needs | Distributed-system and coordination complexity |
Service Boundaries Are the Architecture
The highest-leverage design choice is where one service stops and another begins. A practical starting point is domain-driven design: map business capabilities and bounded contexts before mapping deployment units. Microsoft Azure’s current architecture guidance similarly recommends designing around business capabilities rather than horizontal technical layers such as data access or messaging. Microsoft Azure architecture guidance
A useful boundary has high cohesion inside the service and low coupling outside it. For example, a commerce platform may have distinct concepts for catalog, ordering, payment, and fulfillment. Those areas can often evolve at different speeds and may have different scaling profiles. By contrast, splitting ‘controllers,’ ‘business logic,’ and ‘database access’ into separate services usually creates chatty calls across technical layers and makes almost every feature cross multiple services.
The strongest signal that a boundary is wrong is change coupling. Look at six to twelve months of actual work: which modules change together, which teams coordinate releases, which tables are touched by the same business transaction, and which failures propagate across the same path. Those patterns reveal architecture more reliably than drawing boxes from an org chart.
A boundary should pass more than a diagram test. It should survive actual change and failure.
| Boundary test | Healthy signal | Warning signal |
| Business capability | Service owns a complete, meaningful business responsibility | Service mirrors a technical layer such as controllers or repositories |
| Change coupling | Most changes stay inside one service | Features routinely require synchronized multi-service releases |
| Data ownership | Writes are controlled by the owning service | Several services write directly to the same tables |
| Failure isolation | Downstream failure can be contained or degraded | One slow dependency stalls a wide request chain |
| Team ownership | One team can operate and evolve the service end to end | Ownership is split across teams for every change |
Data Ownership Is the Hidden Test of Autonomy
Data ownership is where many microservices programs stop being independent in practice. If several services write to the same schema, the database becomes the hidden monolith. Schema changes require coordination, one team’s query can overload another team’s workload, and business rules leak across boundaries.
A stronger model gives each service authority over its own data and exposes behavior through an API or events. That does not mean every service needs a physically separate database server. It means other services should not depend on its private schema as an integration contract. The distinction preserves autonomy while avoiding unnecessary infrastructure sprawl.
The trade-off is consistency. A single ACID transaction across many service-owned databases is no longer the default tool. Workflows such as order creation and payment may use sagas, outbox patterns, idempotent consumers, or compensating actions. The business must also decide where eventual consistency is acceptable. That is a domain decision, not merely a messaging choice.
The Distributed-System Tax Arrives Before the Payoff
Microservices move complexity; they do not remove it. The local code inside one service can become easier to reason about while the system as a whole becomes harder to observe and operate. Teams must answer questions that a single-process application could postpone: Which version of an API is compatible? How is a request traced across ten services? What happens when a downstream dependency is slow but not dead? How are secrets rotated? Which team owns an alert at 2 a.m.?
The economic pattern is also asymmetric. The distributed-system tax arrives as soon as the second or third service appears. Independent scaling, independent release cadence, and fault isolation deliver the most value later, when traffic, team count, and domain complexity are high enough to exploit them. That makes premature decomposition especially expensive for small products.
The table below separates benefits that require scale from costs that appear almost immediately.
| Area | Potential payoff | Permanent cost to manage |
| Deployment | Release one capability without redeploying the whole application | API compatibility, versioning, release automation |
| Scaling | Add capacity only where load exists | More runtime units, capacity planning, autoscaling signals |
| Resilience | Isolate some failures by service boundary | Timeouts, retries, circuit breakers, backpressure, degraded modes |
| Data | Choose storage per bounded context | Eventual consistency, duplicated views, saga or outbox patterns |
| Teams | Enable clearer service ownership | Cross-service governance and incident coordination |
Cloud-Native Maturity Does Not Eliminate Complexity
The infrastructure ecosystem has matured significantly. The Cloud Native Computing Foundation reported in January 2026 that 82% of container users run Kubernetes in production, up from 66% in 2023. That makes orchestration a proven platform option rather than an experimental bet. But maturity should not be confused with simplicity. CNCF’s 2024 survey also reported service-mesh adoption falling from 50% in 2023 to 42% in 2024, citing operational overhead as a concern. CNCF Annual Cloud Native Survey
This is a useful warning against architecture by toolchain. Kubernetes can schedule and recover containers, but it does not choose the correct service boundaries, resolve business-level consistency, define API ownership, or decide whether a call should be synchronous. A service mesh can add traffic policy and telemetry, but it cannot compensate for a domain that has been split too finely.
Operational readiness therefore matters as much as code structure. Before decomposing aggressively, teams should have automated deployments, centralized logs, distributed tracing or equivalent correlation, metrics tied to service objectives, secret management, contract testing, and clear ownership. Without those basics, each new service multiplies uncertainty during incidents.
When a Modular Monolith Is the Better Choice
Microservices are not the opposite of good architecture. A well-structured monolith can provide strong modularity with fewer failure modes. For many new products, a modular monolith is the better starting point because boundaries can be enforced in code while deployment remains simple. Services can be extracted later when evidence shows that a module needs separate scaling, ownership, release cadence, or technology.
This is also consistent with modern delivery research. The 2024 DORA report found that platform engineering can improve productivity, yet it can also reduce throughput and stability when poorly implemented or overly mandated. The broader lesson applies directly to architecture: adding a platform or distributed structure does not create performance by itself. The design must reduce a real constraint for the teams using it.
The DORA finding is a useful reminder that architectural sophistication must be judged by delivery outcomes rather than tool adoption alone. DORA 2024 research
A Safer Migration Path: Extract Bottlenecks, Not Everything
Migration should begin with a bottleneck, not a rewrite. The Strangler Fig pattern places new capability around or beside the monolith, routes a narrow slice of traffic to the new service, and gradually retires the old path. This keeps value flowing while the team learns where contracts and data boundaries really belong.
Good first extraction candidates are usually capabilities with clear inputs and outputs, independent scaling pressure, frequent change, or a distinct compliance or reliability requirement. Bad first candidates are deeply entangled shared data models, central authentication logic that every path depends on, or cross-cutting code with unclear ownership.
A migration should also define a rollback point. If extracting one capability requires synchronized changes across half the monolith, the boundary is probably not ready. Refactoring the monolith to create a cleaner internal seam may be the correct first step.
A Practical Readiness Gate Before You Split
- Name the business capability and the team that will own it. If ownership is shared by default, independence will be difficult.
- Map the data boundary. Identify which writes, invariants, and transactions must stay together before choosing APIs or events.
- Prove independent deployment. A service that requires synchronized releases with neighbors has not achieved the main architectural benefit.
- Instrument the request path. Logs should carry correlation identifiers, and critical paths should have metrics and tracing before service count rises.
- Define failure behavior. Specify timeouts, retries, idempotency, queues, fallbacks, and acceptable degraded modes rather than assuming the network works.
- Measure the reason for extraction. Record deployment delay, scaling cost, reliability incidents, or ownership friction so the migration can be judged against a baseline.
The Future of Microservices Architecture in 2027
By 2027, the important shift is likely to be less about whether organizations use microservices and more about how much platform complexity they hide from product teams. Kubernetes is already a common operating layer, and the 2026 CNCF survey shows cloud-native techniques are broadly established. The next competitive advantage is therefore not another orchestration feature; it is making safe defaults, observability, security, and deployment workflows available without forcing every application team to become infrastructure specialists.
Two trends matter. First, internal developer platforms will keep absorbing repetitive concerns such as templates, deployment policy, secrets, telemetry, and golden paths. Second, AI-assisted development will increase code production but may increase change volume and system complexity at the same time. DORA’s 2024 findings already show that productivity gains from AI can coexist with delivery-stability trade-offs. A service architecture with weak boundaries will not become safer simply because code is generated faster.
The likely 2027 winner is disciplined optionality: modular systems that can stay together when that is cheaper and separate only when independent deployment, scaling, or ownership has measurable value. The architecture becomes less ideological and more evidence-driven.
Takeaways
- The best service boundary is a business boundary that can change independently, not the smallest deployable component.
- Data ownership is a stronger autonomy test than repository count; shared writes recreate coupling behind an API facade.
- Network failure, retries, tracing, consistency, and incident ownership are permanent costs, not temporary migration problems.
- Kubernetes maturity lowers platform risk but does not remove domain-design or operational complexity.
- Modular monoliths preserve simple operations while creating seams that can later become service boundaries.
- Incremental extraction through a Strangler Fig pattern reduces rewrite risk and exposes weak boundaries early.
- The decision should be tied to measurable constraints such as release coordination, scaling, reliability, or team ownership.
Conclusion
Microservices architecture earns its keep when independence is valuable enough to pay for distribution. Clear business boundaries, service-owned data, automated delivery, strong observability, and team ownership turn that trade into leverage. Without them, the same decomposition can produce more network calls, more incidents, more coordination, and slower delivery.
The most defensible starting point is therefore not ‘microservices by default.’ It is modularity by default, with distribution introduced where evidence supports it. New systems can begin as well-structured modular monoliths. Existing monoliths can extract capabilities incrementally when scaling, release coordination, reliability, or organizational ownership becomes a real constraint.
That approach is less dramatic than a full rewrite, but it is usually more durable. It keeps the architectural goal focused on business change and system behavior rather than service count. In 2026, the cloud-native toolchain is mature enough to run microservices well. The harder question remains the same: which boundaries deserve to become network boundaries at all?
FAQ
What is a microservice architecture in simple terms?
It is a software design style that builds an application from independently deployable services aligned to business capabilities. Each service exposes a clear contract and can usually be changed, deployed, or scaled without redeploying the whole application. The hard part is preserving that independence across data, APIs, operations, and team ownership.
What is the difference between microservices and a monolith?
A monolith is deployed as one application unit, even if its code is modular. Microservices are deployed as separate services that communicate over a network. The monolith is simpler to operate and transact across; microservices can provide stronger independent deployment and scaling but add network, observability, consistency, and coordination costs.
Are microservices always better for scalability?
No. It helps when specific parts of a system have very different load profiles, because those services can scale independently. A monolith can also scale horizontally, and it may be cheaper when most components grow together. The right test is whether independent scaling changes infrastructure cost, reliability, or performance enough to justify extra complexity.
Does every microservice need its own database?
Every service should own its data contract, but that does not always require a separate physical database server. Separate schemas or databases can be used depending on risk and scale. The key rule is that other services should not treat a service’s private tables as their public integration API.
Do microservices require Kubernetes?
No. Services can run on virtual machines, managed containers, serverless platforms, or other orchestrators. Kubernetes is common because it provides scheduling, health management, rollout, and scaling primitives, but adopting Kubernetes does not automatically make an application well-designed or appropriately decomposed.
When should a team move from a modular monolith to microservices?
Consider extraction when a module has a clear boundary and suffers from a measurable constraint: independent scaling needs, release bottlenecks, distinct reliability requirements, separate ownership, or a technology requirement that is difficult to satisfy inside the monolith. If the reason is only fashion or codebase size, improve modularity first.
Methodology
Research used current primary guidance from Microsoft Azure, AWS, Google Cloud, Martin Fowler, Oracle, Red Hat, Atlassian, IBM, Kong, and CNCF, plus DORA delivery research. The structure was built independently around architecture decisions rather than competitor heading order.
This article was drafted with AI assistance and reviewed by a human editor before publishing. All data, citations, and claims have been independently verified against primary sources.
References
Cloud Native Computing Foundation. (2025, April 1). Cloud Native 2024: Approaching a decade of code, cloud, and change.
Cloud Native Computing Foundation. (2026, January 20). Kubernetes established as the de facto operating system for AI as production use hits 82% in 2025 CNCF Annual Cloud Native Survey.
DORA. (2024). Accelerate State of DevOps Report 2024. Google Cloud.
Fowler, M., & Lewis, J. (2014, March 25). Microservices. MartinFowler.com.
Microsoft. (2026). Microservices architecture style. Azure Architecture Center.
Microsoft. (2026). Use domain analysis to model microservices. Azure Architecture Center.